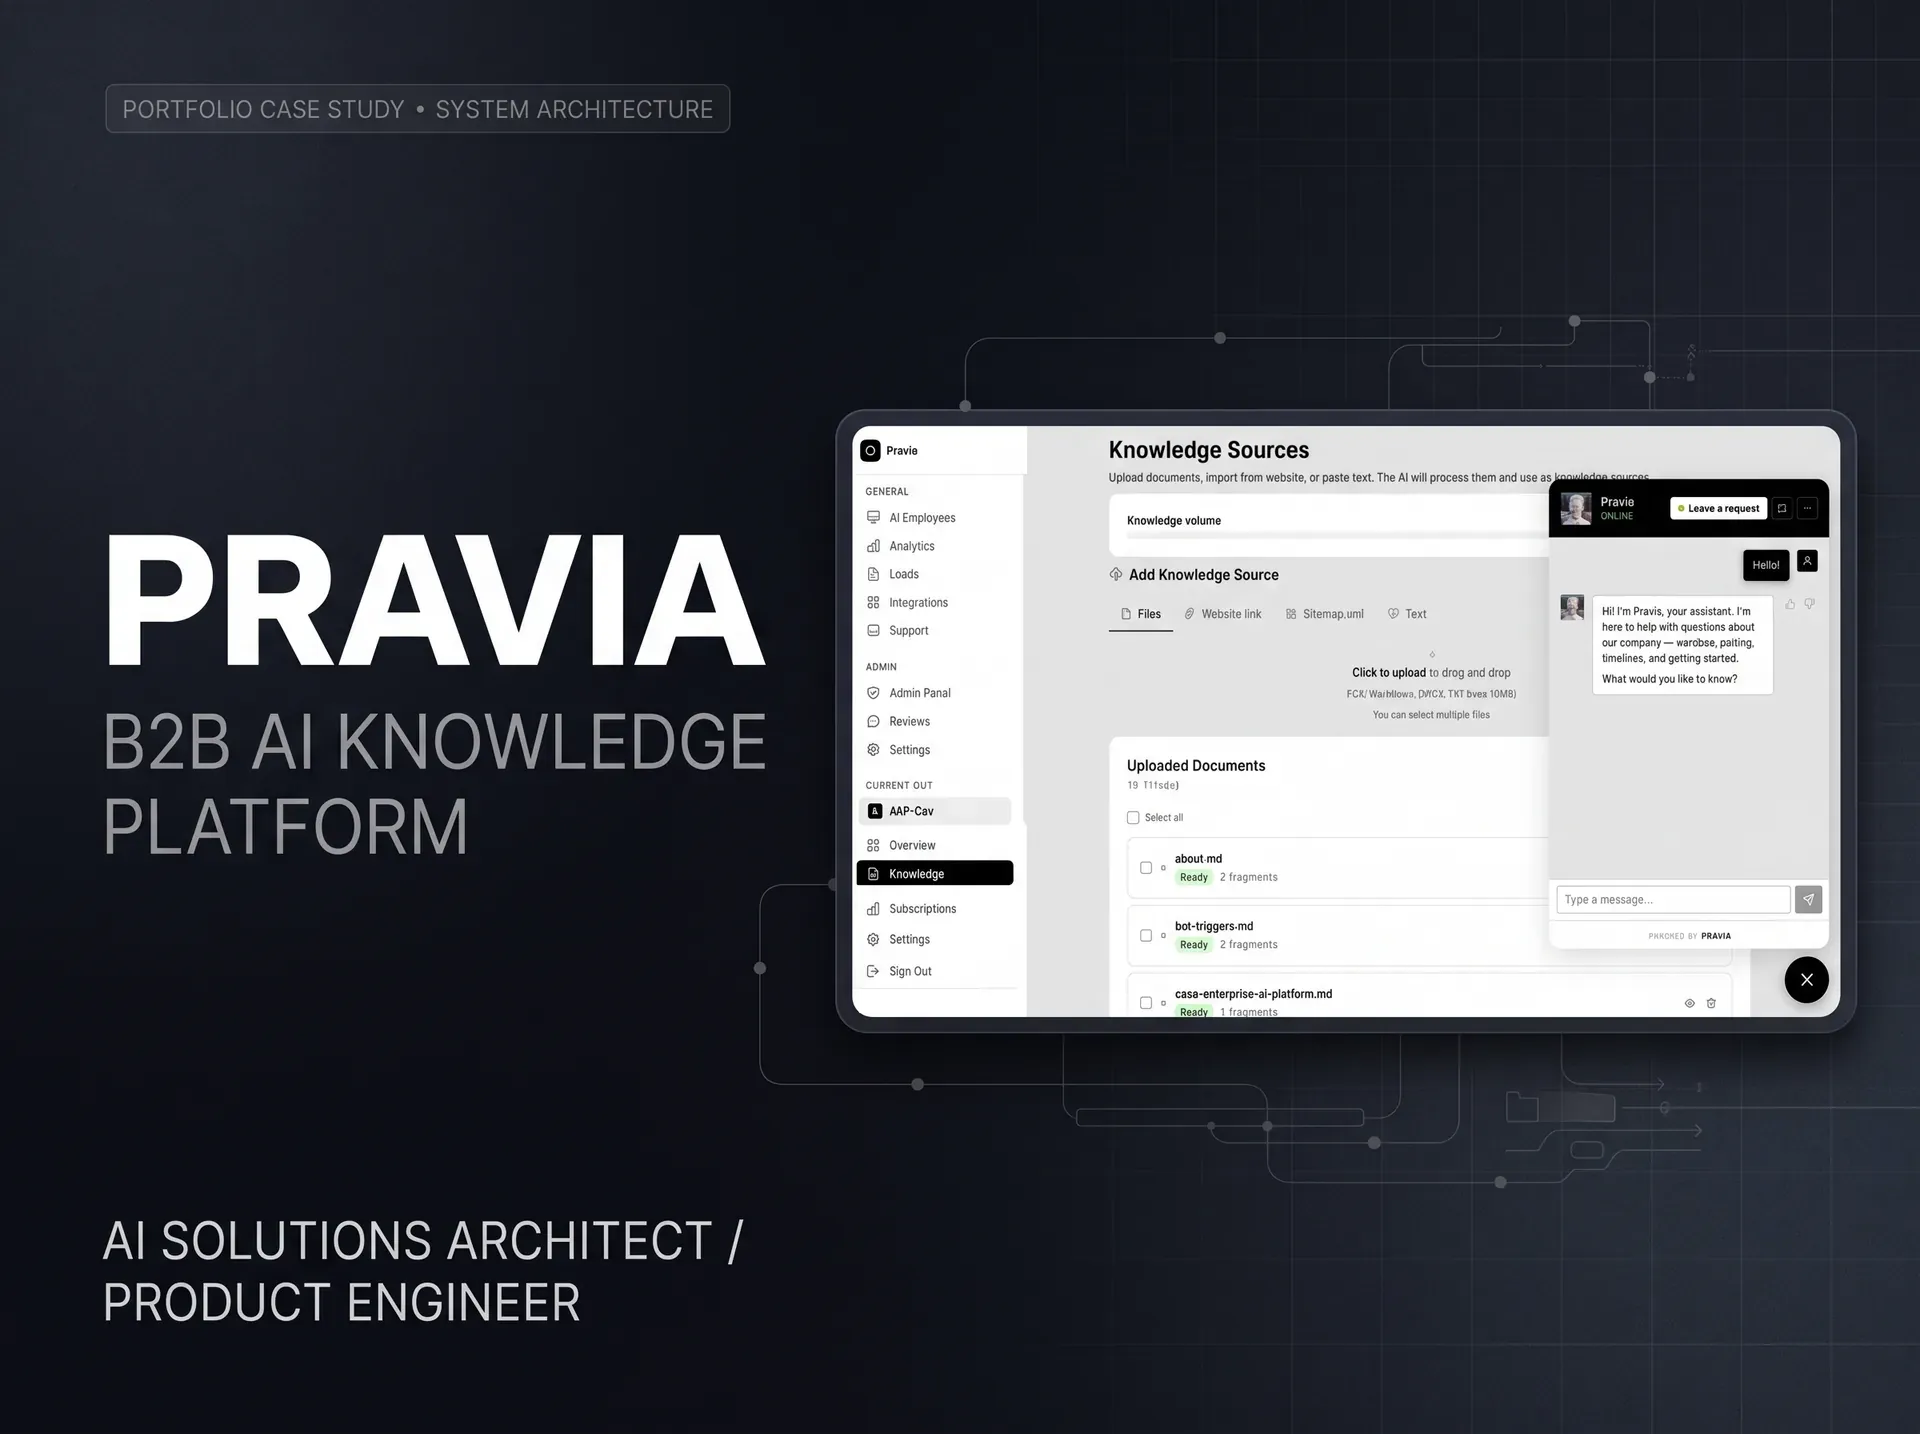
Pravia: Enterprise B2B AI Knowledge & Employee Platform
High-throughput multi-tenant RAG platform powered by on-device ONNX embeddings and pgvector (HNSW), slashing p95 latency from 19.7s to 164ms under 1,000 VU stress.
Client
Proprietary Product / B2B SaaS
Services
Multi-Tenant RAG Architecture, Vector Search, Local Embeddings, k6 Load Testing
Service
Task
Most turnkey RAG solutions suffer from high latency and token costs caused by external embedding APIs, throughput collapse under concurrent traffic, and insufficient data isolation across enterprise clients. The objective was to engineer an autonomous, multi-tenant B2B platform capable of deploying AI employees that resolve customer inquiries and support staff based strictly on uploaded SOPs, manuals, and websites with sub-second response times under heavy production load.
Solution
The Pravia architecture is built on Bun and PostgreSQL with pgvector. Query vectorization runs locally on CPU via ONNX Runtime using EmbeddingGemma-300M, removing external API network roundtrips and cutting compute overhead by up to 90%. Vector lookups leverage PostgreSQL with HNSW graph indexing, ensuring sub-millisecond retrieval across dense enterprise document collections. Responses stream progressively via SSE (Server-Sent Events) for near-instantaneous Time to First Token (TTFT).
Architecture Dataflow
┌─────────────────────────┐          SSE Streaming          ┌──────────────────────────┐
│   Web / Telegram Chat   │ ◄────────────────────────────── │   Pravia Response Engine │
└────────────┬────────────┘                                 └────────────▲─────────────┘
             │                                                           │
             │ Query Text                                                │ Top-K Chunks
             ▼                                                           │
┌─────────────────────────┐      Sub-ms Vector Search       ┌──────────────────┴─────────────┐
│   ONNX Runtime (CPU)    │ ──────────────────────────────► │   PostgreSQL 16 + pgvector     │
│   EmbeddingGemma-300M   │   Zero-Cloud Vectorizer         │   HNSW Index (ef_search = 64)  │
└─────────────────────────┘                                 └────────────────────────────────┘
k6 Benchmark Results
| Metric | Baseline | Post-Optimization (HNSW + Batching) | Outcome |
|---|---|---|---|
| p95 Latency (300 VU) | 19.7 s | 164 ms | 120x Latency Reduction |
| Peak Throughput (1,000 VU) | Connection dropouts | 46 req/s (99.98% OK) | Zero degradations |
| Embedding Infrastructure | Cloud API metering | Zero-Cloud CPU ONNX | 90% Cost Cut |
Key Features
- Zero-Cloud Embeddings: On-device query vectorization via ONNX Runtime (EmbeddingGemma-300M) without sending sensitive context to external APIs.
- pgvector + HNSW Indexing: Fine-tuned HNSW parameters (ef_search, m) deliver sub-millisecond vector retrieval across hundreds of thousands of document chunks.
- Multi-Tenancy & RBAC: Strict cryptographic session scoping and tenant isolation guarantee zero cross-organization data leakage.
- Multi-Format Ingestion: Automated parsing and indexing of websites via Sitemap XML, along with PDF, DOCX, Markdown, and raw text.
- Embeddable Widget & Lead Webhooks: One-line JavaScript embed for websites, real-time Telegram bot gateway, and instant qualified lead dispatch to CRM systems.
Technologies
Architecture and Deployment
Initial stress benchmarks showed p95 latency of 19.7s due to connection pool locks during synchronous logging. Following transaction de-serialization, asynchronous analytics batching, and a dedicated ONNX worker pool, p95 latency settled at 164ms with 0% errors at 300 concurrent users. Under peak load of 1,000 VU, the platform sustained 46 req/s with a 99.98% success rate on a single standard VPS.
Related Projects
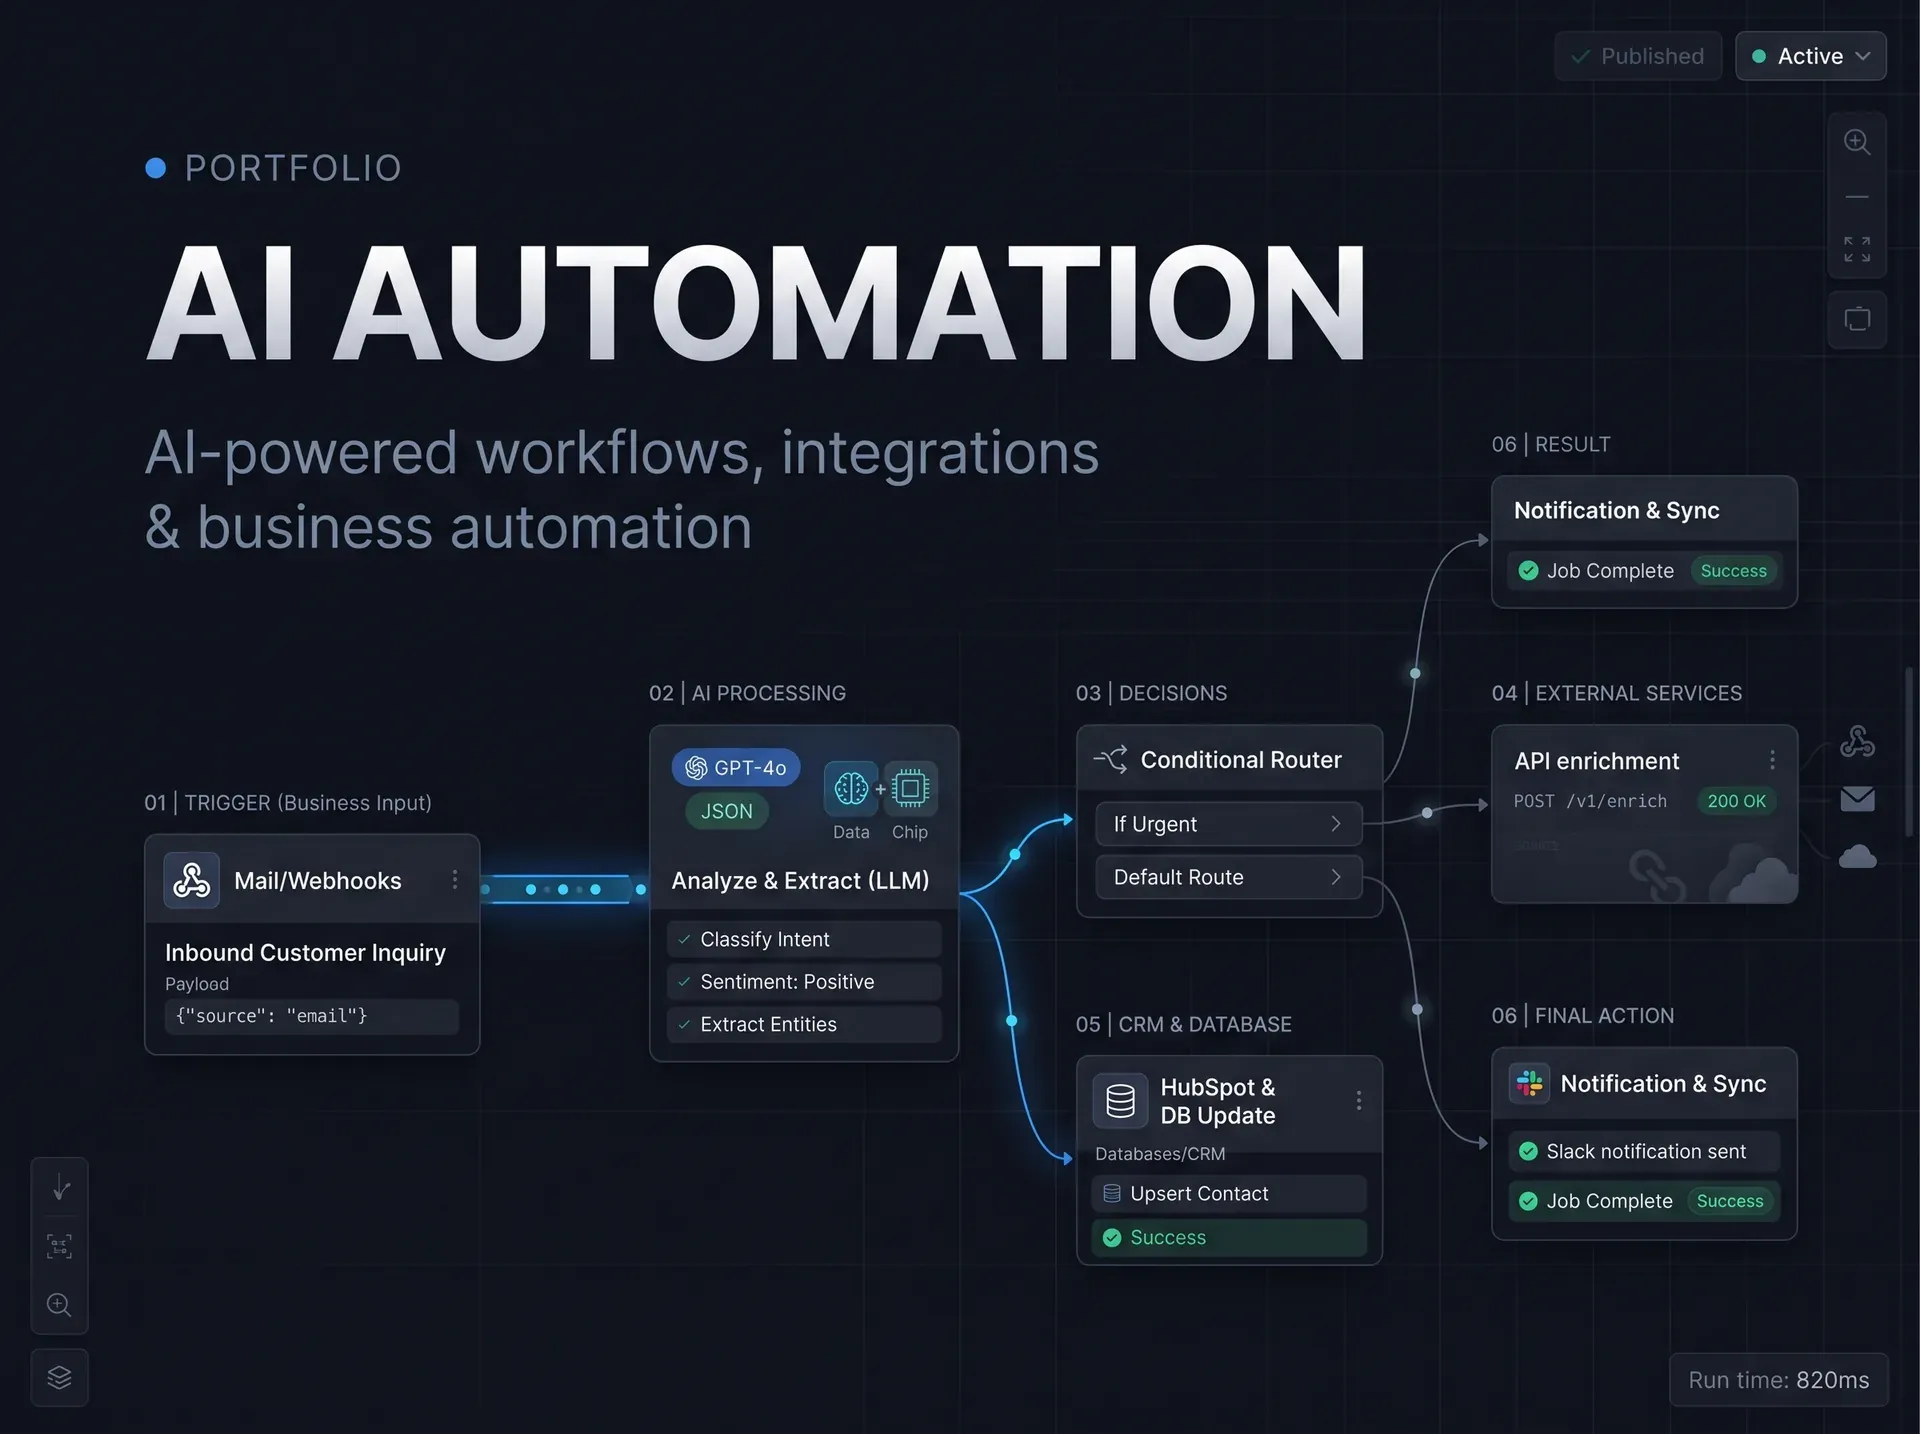
Lead Hunter AI — Autonomous Multichannel Lead-Gen & Scoring Agent
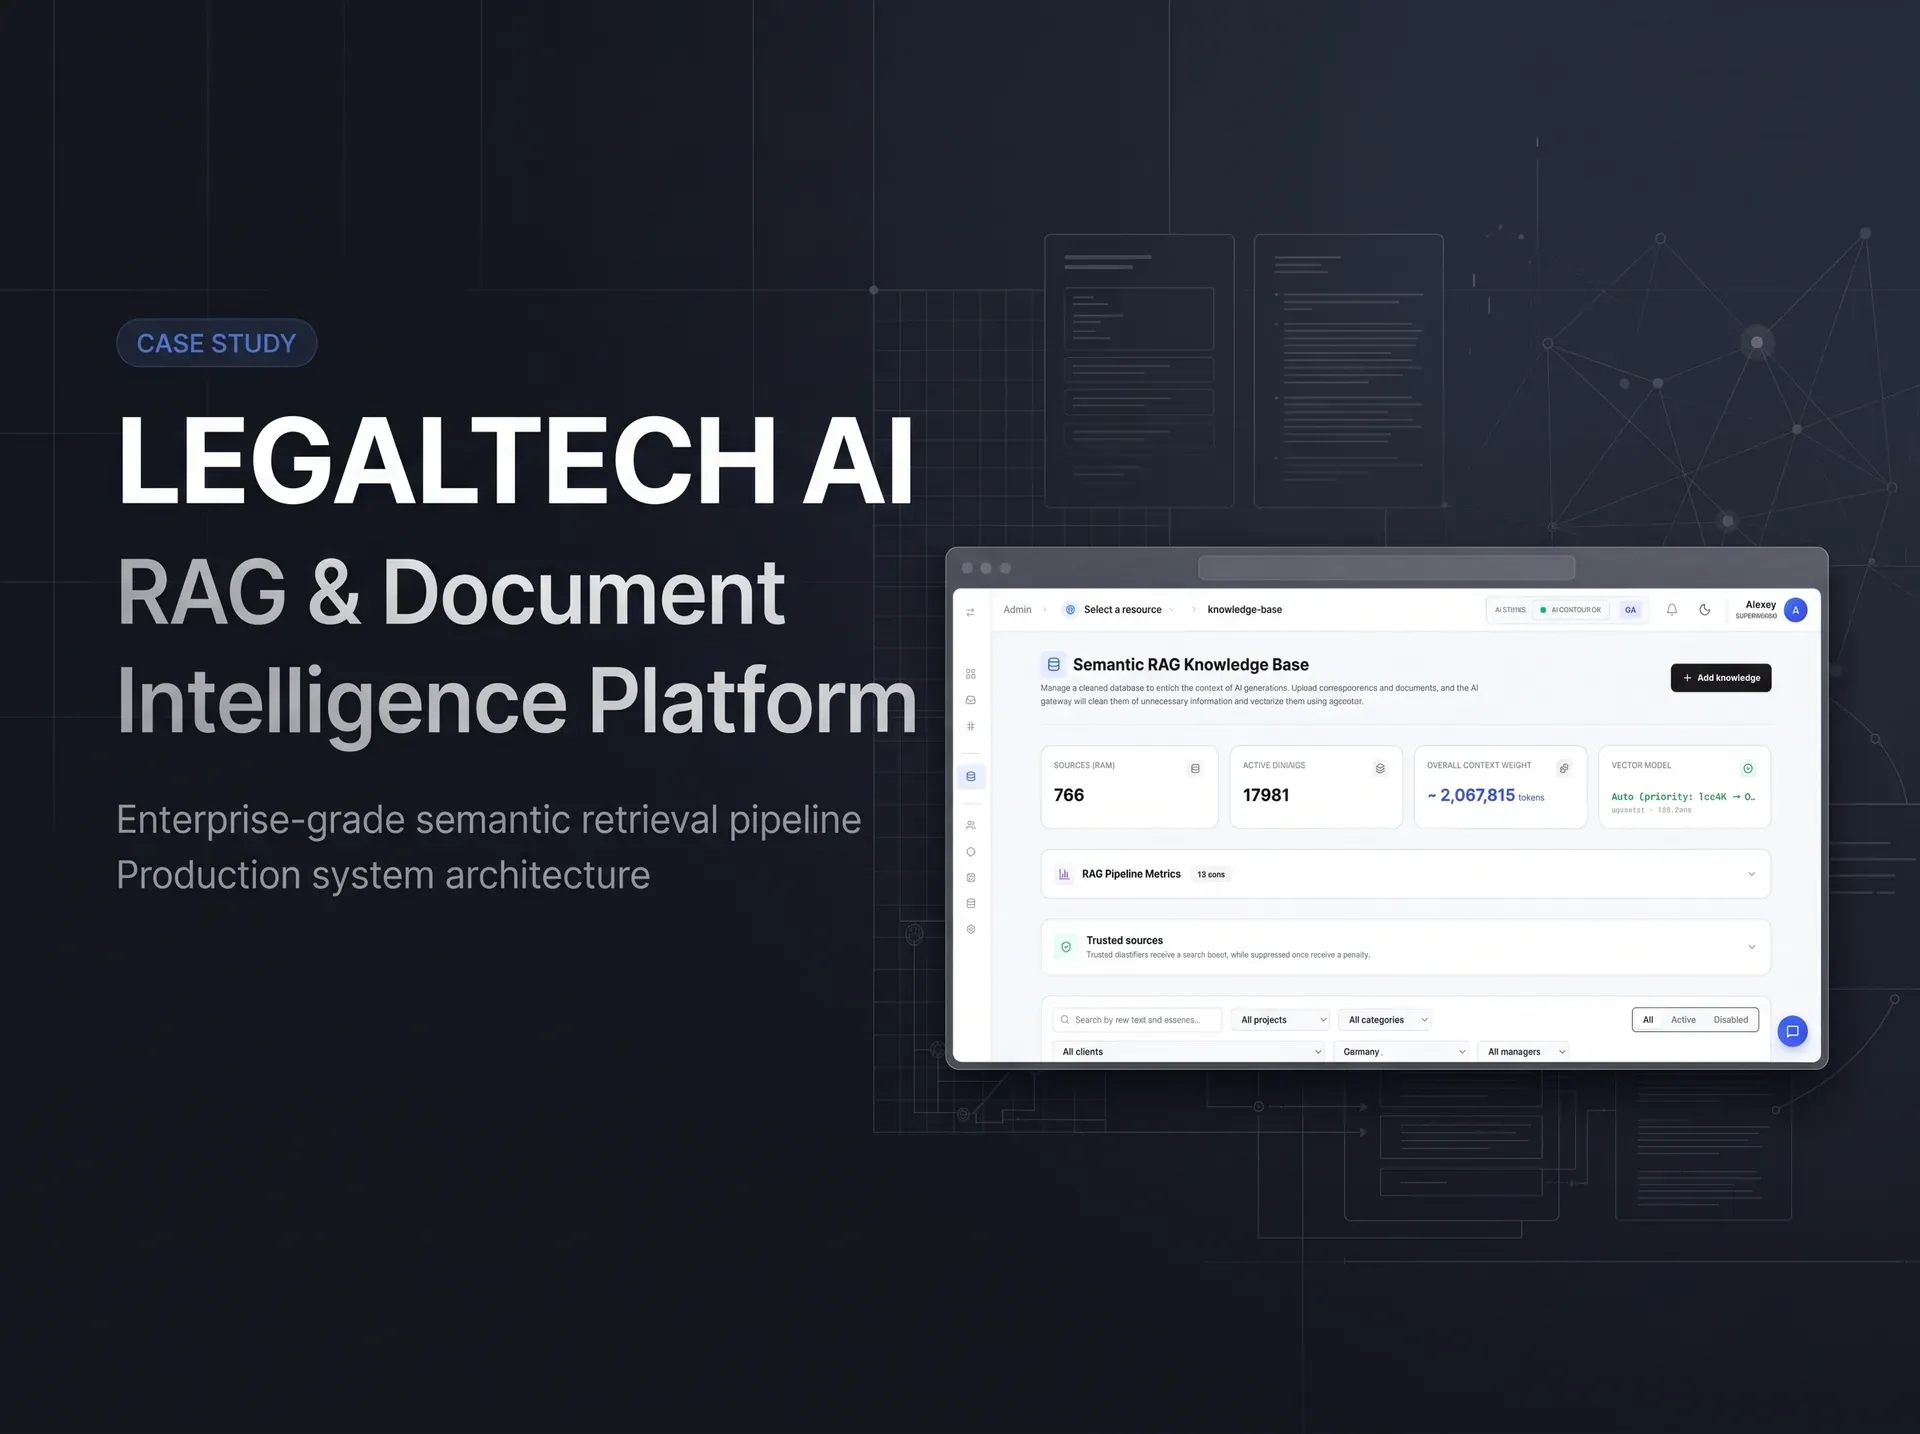
Enterprise RAG — High-Load 65k+ Chunk Knowledge Engine & AI Gateway
Like our engineering approach?
We will architect and deploy a robust system for your business — from architecture to launch and support.