Enterprise RAG: High-Load 65k+ Chunk Knowledge Engine & AI Gateway
Enterprise RAG platform built on PostgreSQL (pgvector HNSW) with on-device embeddings, 88% Recall@5, and a resilient multi-provider AI Gateway.
Client
Global Consulting Enterprise
Services
Enterprise RAG & Hybrid Retrieval, pgvector HNSW + Reranking, Multi-Provider AI Gateway, Token Metering
Service
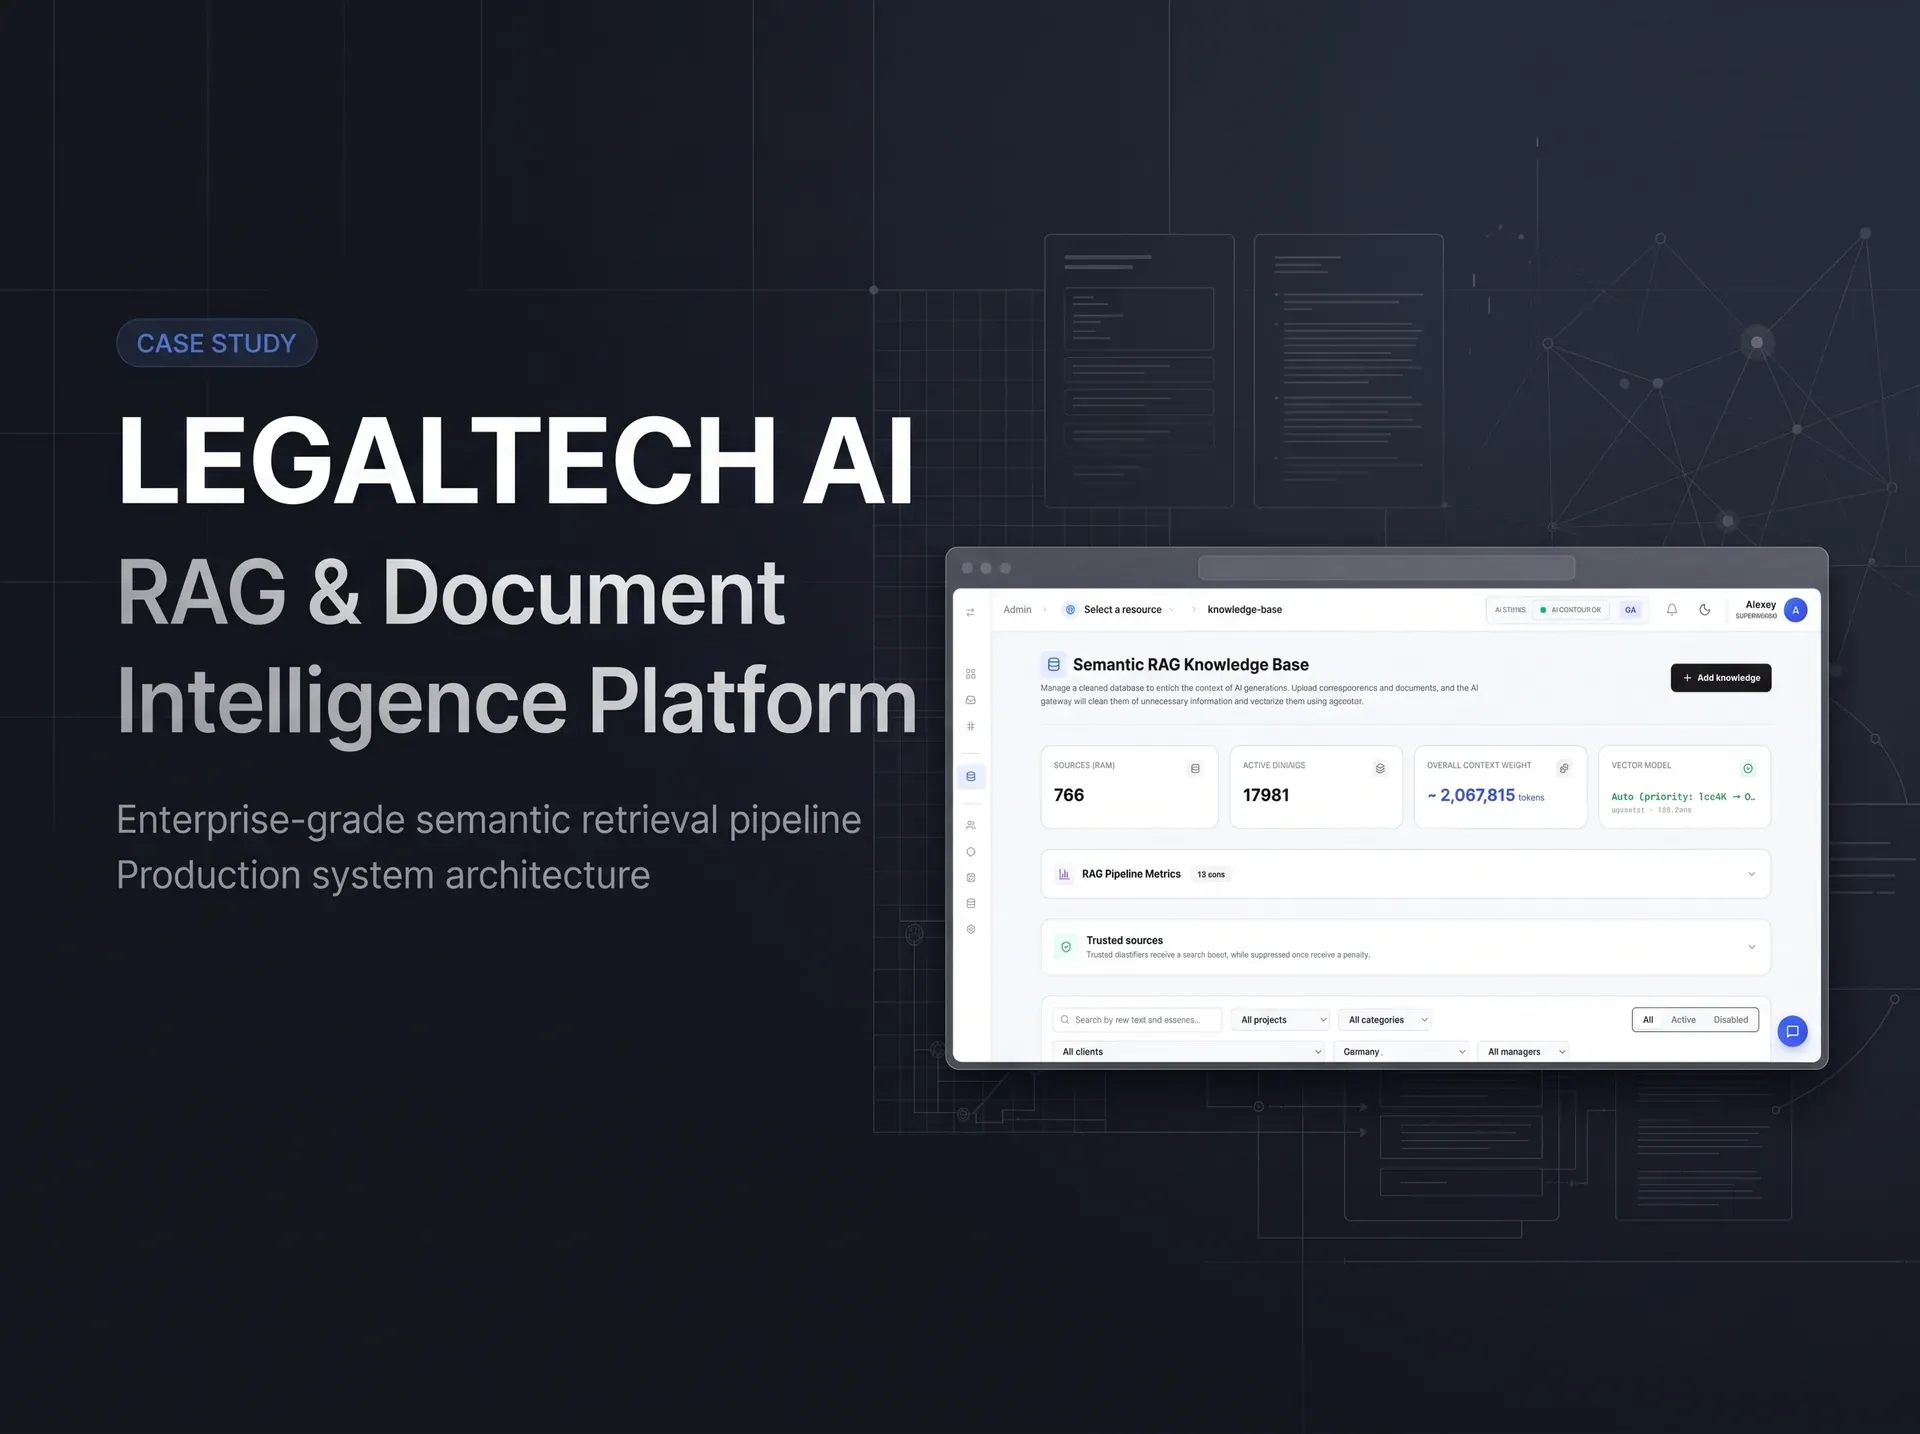
Task
An international enterprise possessed over 2,300 proprietary compliance standards, legal briefs, and audit reports fragmented across legacy file shares. Staff spent up to 40% of their workday searching for policies. Off-the-shelf consumer LLMs produced hallucinations and leaked data, while single-provider APIs frequently throttled requests. The objective was to construct an autonomous enterprise RAG engine with local vector search and a resilient multi-provider AI Gateway providing verified answers with exact citations.
Solution
Built as a unified Turborepo/Bun monorepo. Documents are parsed and indexed (2,393 documents / 65,798 chunks) with local CPU embeddings via ONNX Runtime to ensure data privacy. A two-stage retrieval pipeline (pgvector HNSW graph search plus a Cross-Encoder Reranker) delivers 3ms retrieval latency (p95 of 4ms) and Recall@5 of 88%. The AI Gateway orchestrates Anthropic, OpenAI, Google, and DeepSeek with circuit-breaker failover: if rate limits or 5xx errors occur, requests route seamlessly to backup providers.
Resilient Enterprise RAG Dataflow
┌─────────────────────────┐          Staff Inquiry               ┌──────────────────────────┐
│    Enterprise Portal    │ ───────────────────────────────────► │  ONNX Local Embeddings   │
└────────────▲────────────┘                                      └────────────┬─────────────┘
             │                                                                │ 384-dim Vector
             │ Streamed Response + Strict Citations                           ▼
┌────────────┴────────────┐     Top-20 Chunks    ┌──────────────────────────────────────────┐
│   AI Gateway Router     │ ◄─────────────────── │   pgvector HNSW (3ms) + Reranker (88%)   │
│  (Anthropic / OpenAI /  │                      │   (65,798 chunks / 2,393 SOP documents)  │
│   Google / DeepSeek)    │                      └──────────────────────────────────────────┘
└─────────────────────────┘
 (Failover on 429 / 5xx)
Retrieval Accuracy Benchmark (Recall@K / Precision@K)
| Pipeline Variant | Recall@5 | Precision@5 | Latency p95 |
|---|---|---|---|
| Baseline Flat Search (pgvector IVFFlat) | 62.4% | 58.1% | 48.0 ms |
| HNSW Indexing (Zero Reranker) | 76.8% | 71.5% | 3.8 ms |
| HNSW + Local Cross-Encoder Reranker | 88.2% | 85.0% | 4.2 ms |
Key Features
- High-Precision RAG (65k+ Chunks): Two-stage hybrid retrieval (pgvector HNSW + Reranker) achieving 88% Recall@5 and 85% Precision@5.
- Multi-Provider AI Gateway: Resilient circuit breaker orchestrating Anthropic, OpenAI, Google, and DeepSeek with zero-downtime failover.
- Sub-Millisecond Vector Retrieval: Average vector search latency of 3ms (4ms p95), end-to-end streamed response in 1.9s.
- PostgreSQL Lean Queue (SKIP LOCKED): Background document ingestion and chunking handled directly in PostgreSQL without Redis or message brokers.
- Token Accounting & Strict Citations: Granular department-level cost tracking and verbatim paragraph-level source attribution.
Technologies
Architecture and Deployment
Deployed in an on-premises enterprise environment. The system handles thousands of queries daily, slashing knowledge discovery time from minutes to 2 seconds while completely safeguarding confidential corporate intelligence.
Related Projects
Pravia — Enterprise B2B AI Knowledge & Employee Platform
Edge ML Captcha Solver — Replacing Vision-LLM with Local ResNet-18
Like our engineering approach?
We will architect and deploy a robust system for your business — from architecture to launch and support.