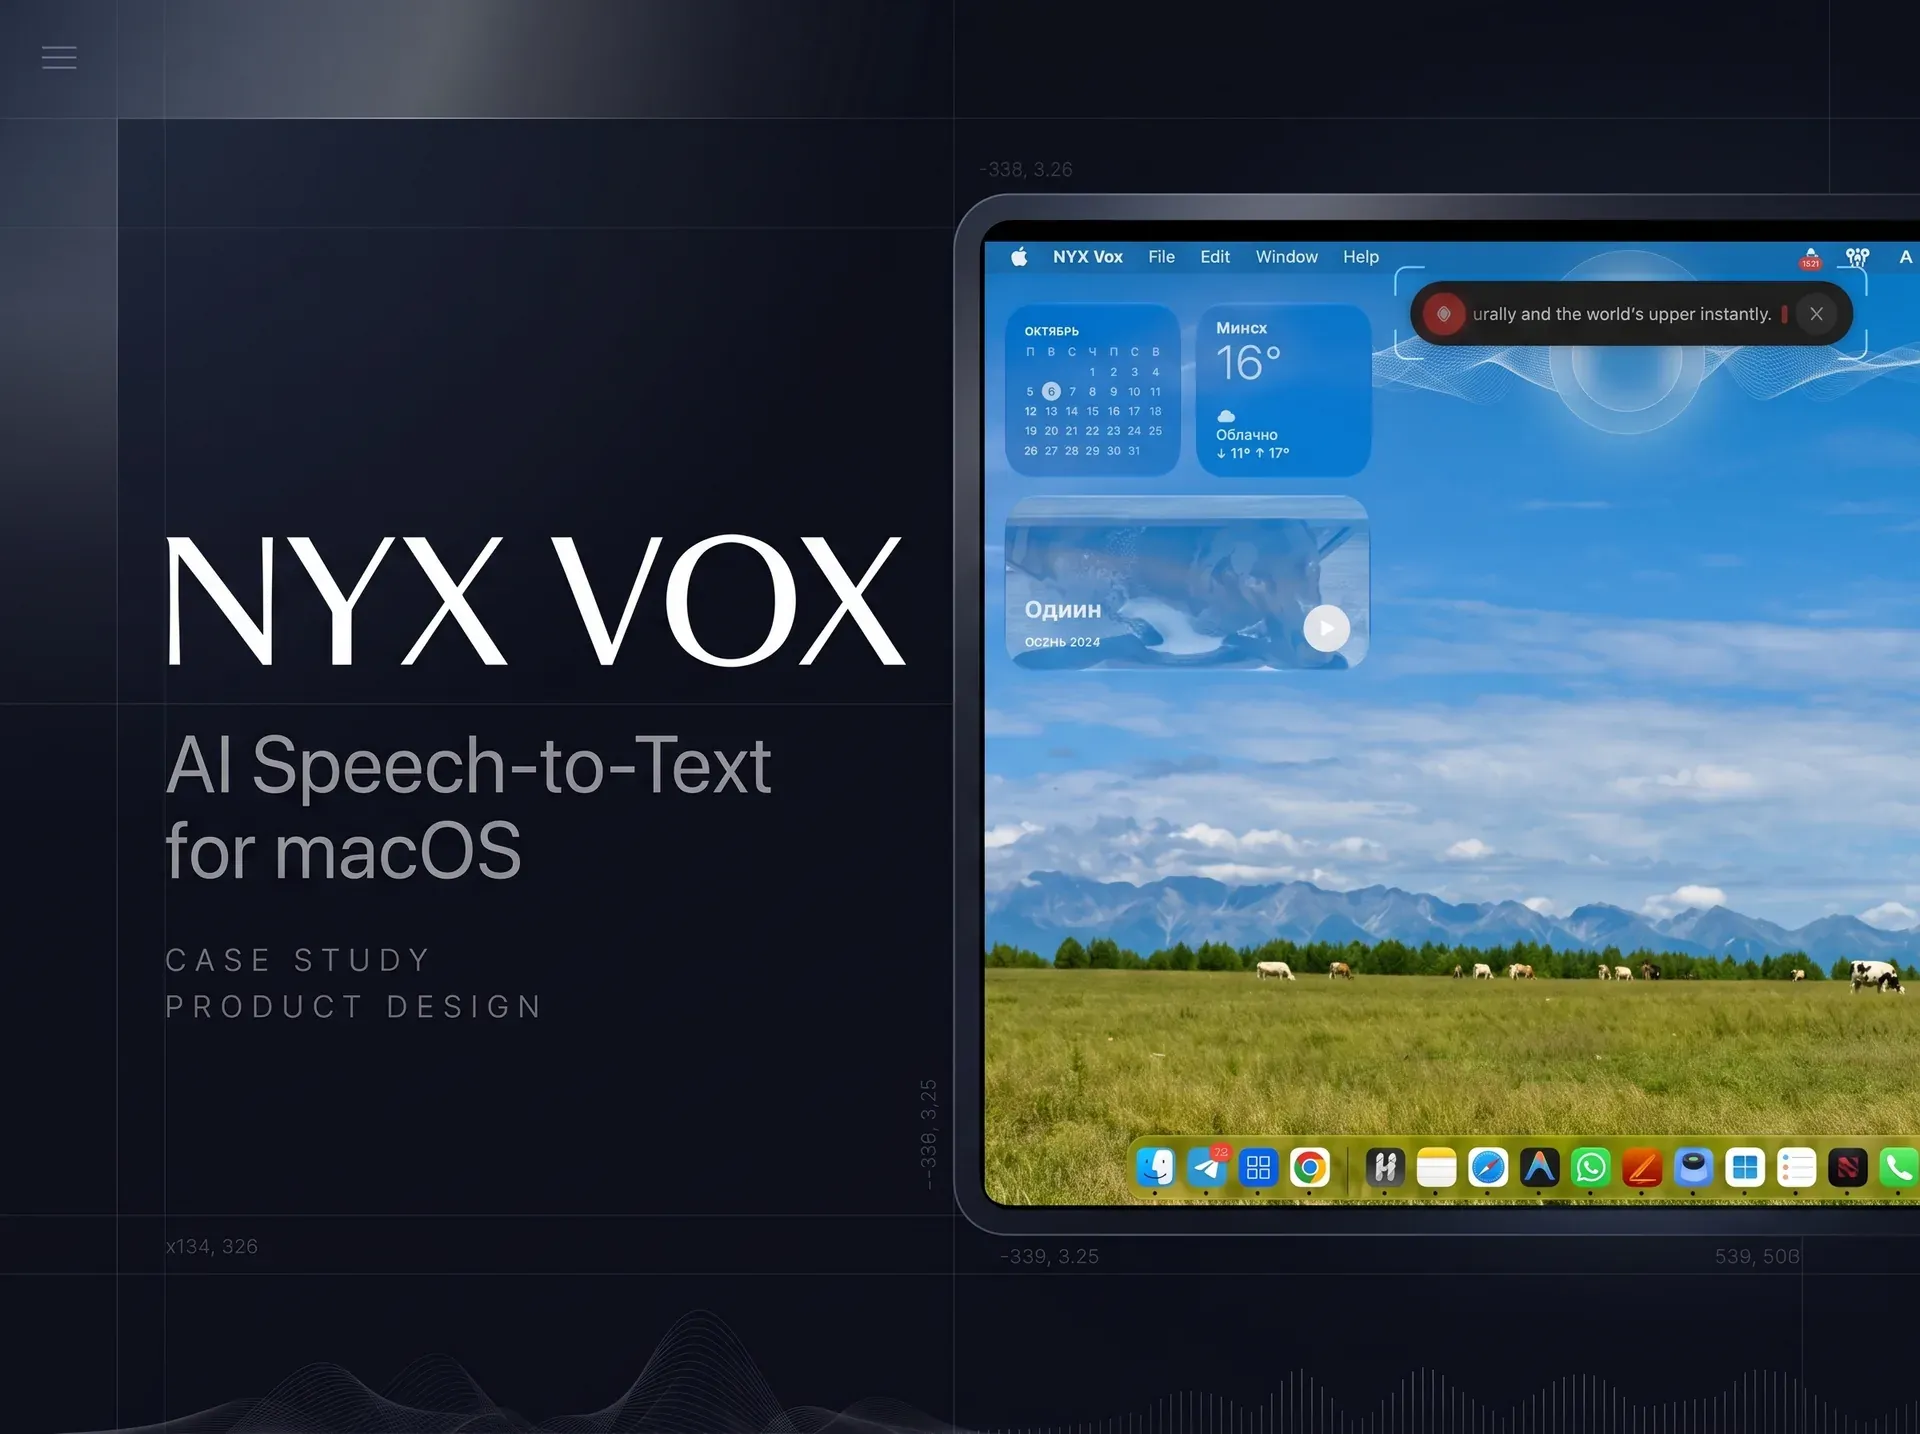
NYX Vox: Native Desktop AI Voice Interface (< 500ms)
Cross-platform desktop application built on Rust and Tauri 2: speech to structured text in under 500ms with verbatim AI formatting and instant auto-paste into active applications.
Client
Open Source / Proprietary Product
Services
Systems Programming (Rust / Tauri 2), Low-Latency Audio DSP, Multi-Engine STT, OS HID Injection
Service
Task
Conventional desktop speech-to-text tools create friction for engineers and technical writers: 3–5 second turnaround times interrupt thought flow, transcripts lack punctuation and structure, and users must dictate into a dedicated window before manually copying back. The objective was to engineer a lightweight native desktop tool for macOS and Windows with sub-second turnaround, verbatim formatting without hallucinated edits, and direct caret injection into the active window.
Solution
NYX Vox combines Rust 2021 (Tauri 2) systems architecture with a Next.js 16 / React 19 interface. Audio capture runs on an isolated native thread via cpal with minimal buffer allocations. Smart VAD and a calibrated Noise Gate backed by a 300ms pre-speech FIFO buffer eliminate clipping. Ultra-low latency cloud LPUs (Groq Whisper Turbo ~500ms) provide instant transcription, backed by on-device local Whisper with Metal / Core ML acceleration for complete offline privacy. LLMs format punctuation while preserving exact vocabulary, and text is injected via macOS Accessibility APIs or Windows SendInput.
Audio Pipeline & Caret Injection Architecture
┌─────────────────┐       ┌────────────────────────┐       ┌──────────────────────┐
│  Audio Capture  │ ────► │  300ms Pre-Speech FIFO │ ────► │  Smart VAD & Noise   │
│  (Rust / cpal)  │       │  Ring Buffer           │       │  Gate Detection      │
└─────────────────┘       └────────────────────────┘       └──────────┬───────────┘
                                                                      │ Clean Audio
                                                                      ▼
┌─────────────────┐       ┌────────────────────────┐       ┌──────────────────────┐
│  Direct HID     │ ◄──── │  Verbatim AI           │ ◄──── │  STT Cloud Turbo /   │
│  Injection      │       │  Refinement (LLM)      │       │  Local Metal Whisper │
└─────────────────┘       └────────────────────────┘       └──────────────────────┘
 (Accessibility / SendInput)
Operational Modes
| Dimension | Cloud LPU (Groq Turbo) | On-Device Local (Metal / Core ML) |
|---|---|---|
| Response Latency | < 500ms | 1.2–2.0s |
| Connectivity | Standard broadband | 0 KB/s (100% Air-Gapped) |
| Security & Privacy | Ephemeral memory, zero logging | 100% on-device neural execution |
| RAM Footprint | ~65 MB (Tauri 2) | ~320 MB (inclusive of model weights) |
Key Features
- Rust Audio DSP Pipeline (cpal): Native system thread capture with a 300ms pre-speech FIFO ring buffer and calibrated smart noise gate.
- Multi-Tier Resilient Fallback: Cascading STT tier (Groq Whisper Turbo ~500ms → Deepgram Nova → on-device Local Whisper via Metal/Core ML for 100% offline privacy).
- 100% Verbatim AI Refinement: Calibrated LLM formatting (DeepSeek, Qwen, Gemini, GigaChat) strictly preserves exact vocabulary and code syntax without paraphrasing.
- Direct HID Injection: Immediate text insertion directly into the active application caret using macOS Accessibility APIs and Windows SendInput.
- Hardware-Bound Vault: API credentials stored locally using AES-256-GCM encryption tied to physical machine hardware signatures.
Technologies
Architecture and Deployment
The Tauri 2 architecture reduces memory overhead by over 80% compared to typical Electron alternatives. The full lifecycle from releasing the global hotkey to rendered, punctuated text appearing in IDEs completes in under 500ms via cloud LPU and 1.2–2.0s in completely offline local mode.
Related Projects
Edge ML Captcha Solver — Replacing Vision-LLM with Local ResNet-18
Enterprise RAG — High-Load 65k+ Chunk Knowledge Engine & AI Gateway
Like our engineering approach?
We will architect and deploy a robust system for your business — from architecture to launch and support.