Edge ML Captcha Solver: Replacing Vision-LLM with Local ResNet-18
Computer vision optimization: accelerating captcha solving 800x on CPU (3.5ms vs 3s), improving accuracy from 30.2% to 75.0% with zero cloud API costs.
Client
Data Extraction & Automation / B2B
Services
Computer Vision & Edge ML Inference, Architecture Optimization (ResNet-18 + SE), ONNX Runtime CPU, Browser Automation
Service
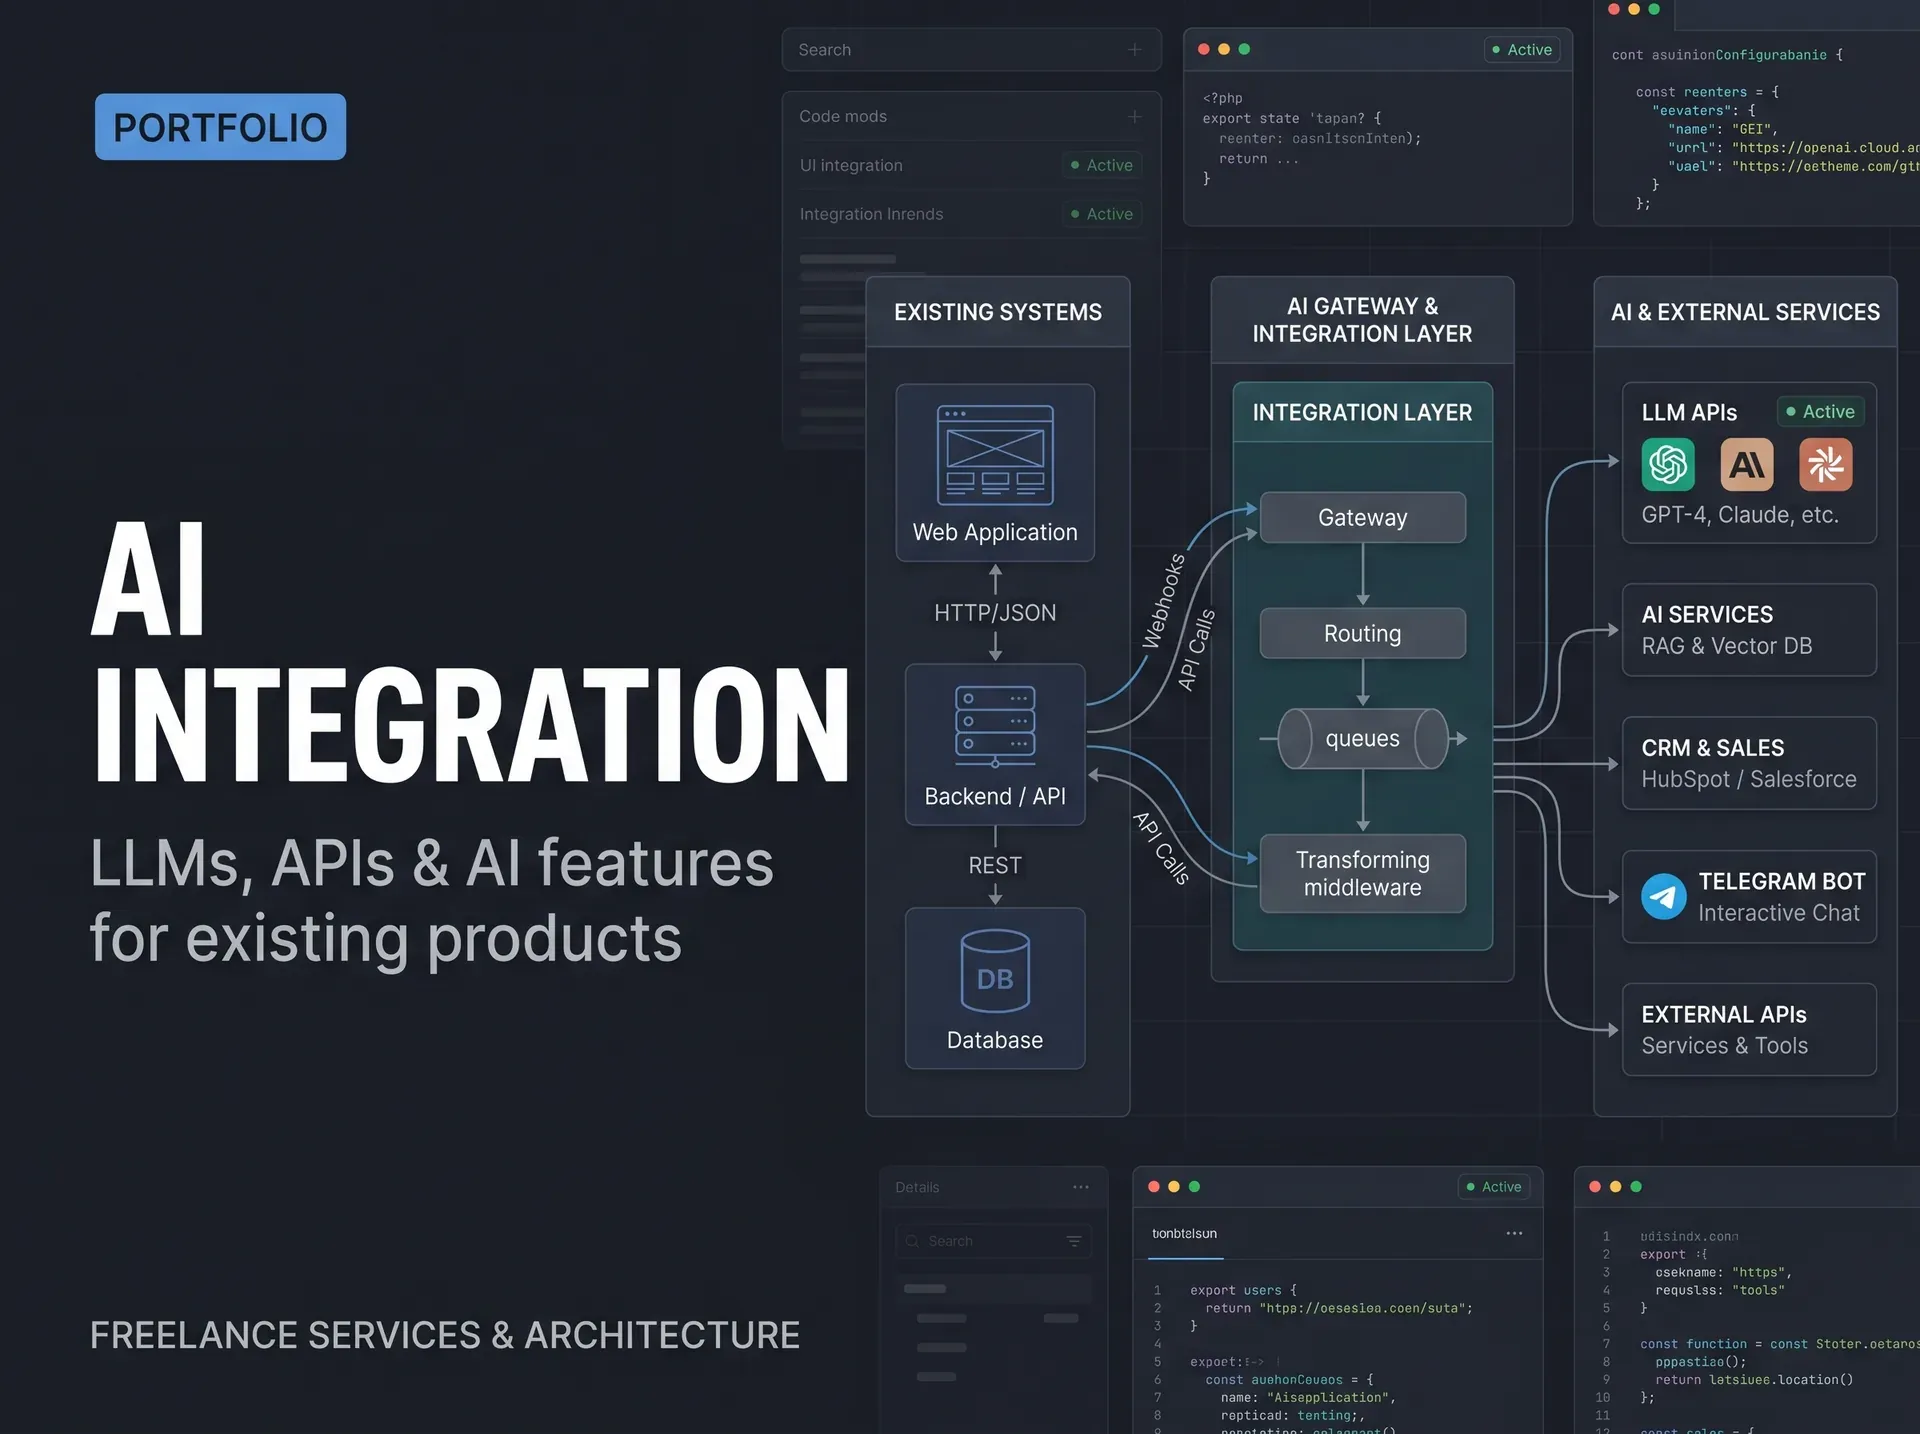
Task
In high-throughput market data extraction workflows, 3x3 grid object segmentations created major bottlenecks. Relying on cloud multimodal Vision-LLMs suffered from three critical flaws: low accuracy (30.2%), excessive latency (~3 seconds), and compounding token costs. The objective was to replace the external LLM with a specialized, lightweight convolutional neural network running on standard CPUs in sub-millisecond time without GPU hardware.
Solution
Curated and annotated a domain dataset of 5,011 real-world captures with balanced augmentation. Implemented a ResNet-18 backbone enhanced with Squeeze-and-Excitation (SE) attention blocks to dynamically re-calibrate channel feature maps under visual noise. Trained in PyTorch, quantized, and exported to ONNX Runtime utilizing CPU AVX2/AVX-512 vectorization. Packaged into a high-performance FastAPI service yielding 3.5ms inference times and paired with a Chrome automation extension.
Computer Vision Edge Inference Dataflow
┌─────────────────────────┐          Intercept Captcha        ┌──────────────────────────┐
│    Chrome / Playwright  │ ────────────────────────────────► │     FastAPI Service      │
│    Scraper Worker       │ ◄──────────────────────────────── │  (3x3 Tile Slicing)      │
└─────────────────────────┘          Click Coordinates        └────────────┬─────────────┘
                                                                           │ 9 Discrete Tiles
                                                                           ▼
                                                              ┌──────────────────────────┐
                                                              │  ONNX Runtime (AVX-512)  │
                                                              │  ResNet-18 + SE (CPU)    │
                                                              │  Latency: 3.5ms / tile   │
                                                              └──────────────────────────┘
Benchmark Comparison
| Metric | Vision-LLM Baseline | Edge Model (ResNet-18 + SE) | Engineering Gain |
|---|---|---|---|
| Exact Match Accuracy | 30.2% | 75.0% | 2.5x Accuracy Boost |
| Per-Tile Latency | ~3,000 ms | 3.5–4.0 ms | ~800x Acceleration |
| Hardware Overhead | Metered cloud token APIs | Standard CPU (AVX2/AVX-512) | $0 Continuous API Invoices |
| Operational Privacy | Dependent on external uptime | 100% on-premise execution | Zero Network Dropouts |
Key Features
- 800x Inference Acceleration: 3.5–4.0ms per tile vs ~3,000ms turnaround for multimodal cloud Vision-LLMs.
- 2.5x Accuracy Increase: Test set Exact Match accuracy jumped from 30.2% to 75.0% on tough visual edge cases.
- ResNet-18 + SE Attention: Channel-wise attention recalibration filters noise and highlights diagnostic textures.
- CPU-Optimized ONNX Runtime: Blazing-fast inference on commoditized CPU cores with zero GPU dependency.
- Zero Cloud API Cost: Eliminates continuous third-party token and captcha solving service fees.
Technologies
Architecture and Deployment
Packaged into a minimal Docker container and integrated into the customer’s autonomous extraction workers. The system processes thousands of challenges daily with zero cloud dependencies and immediate sub-second throughput.
Related Projects
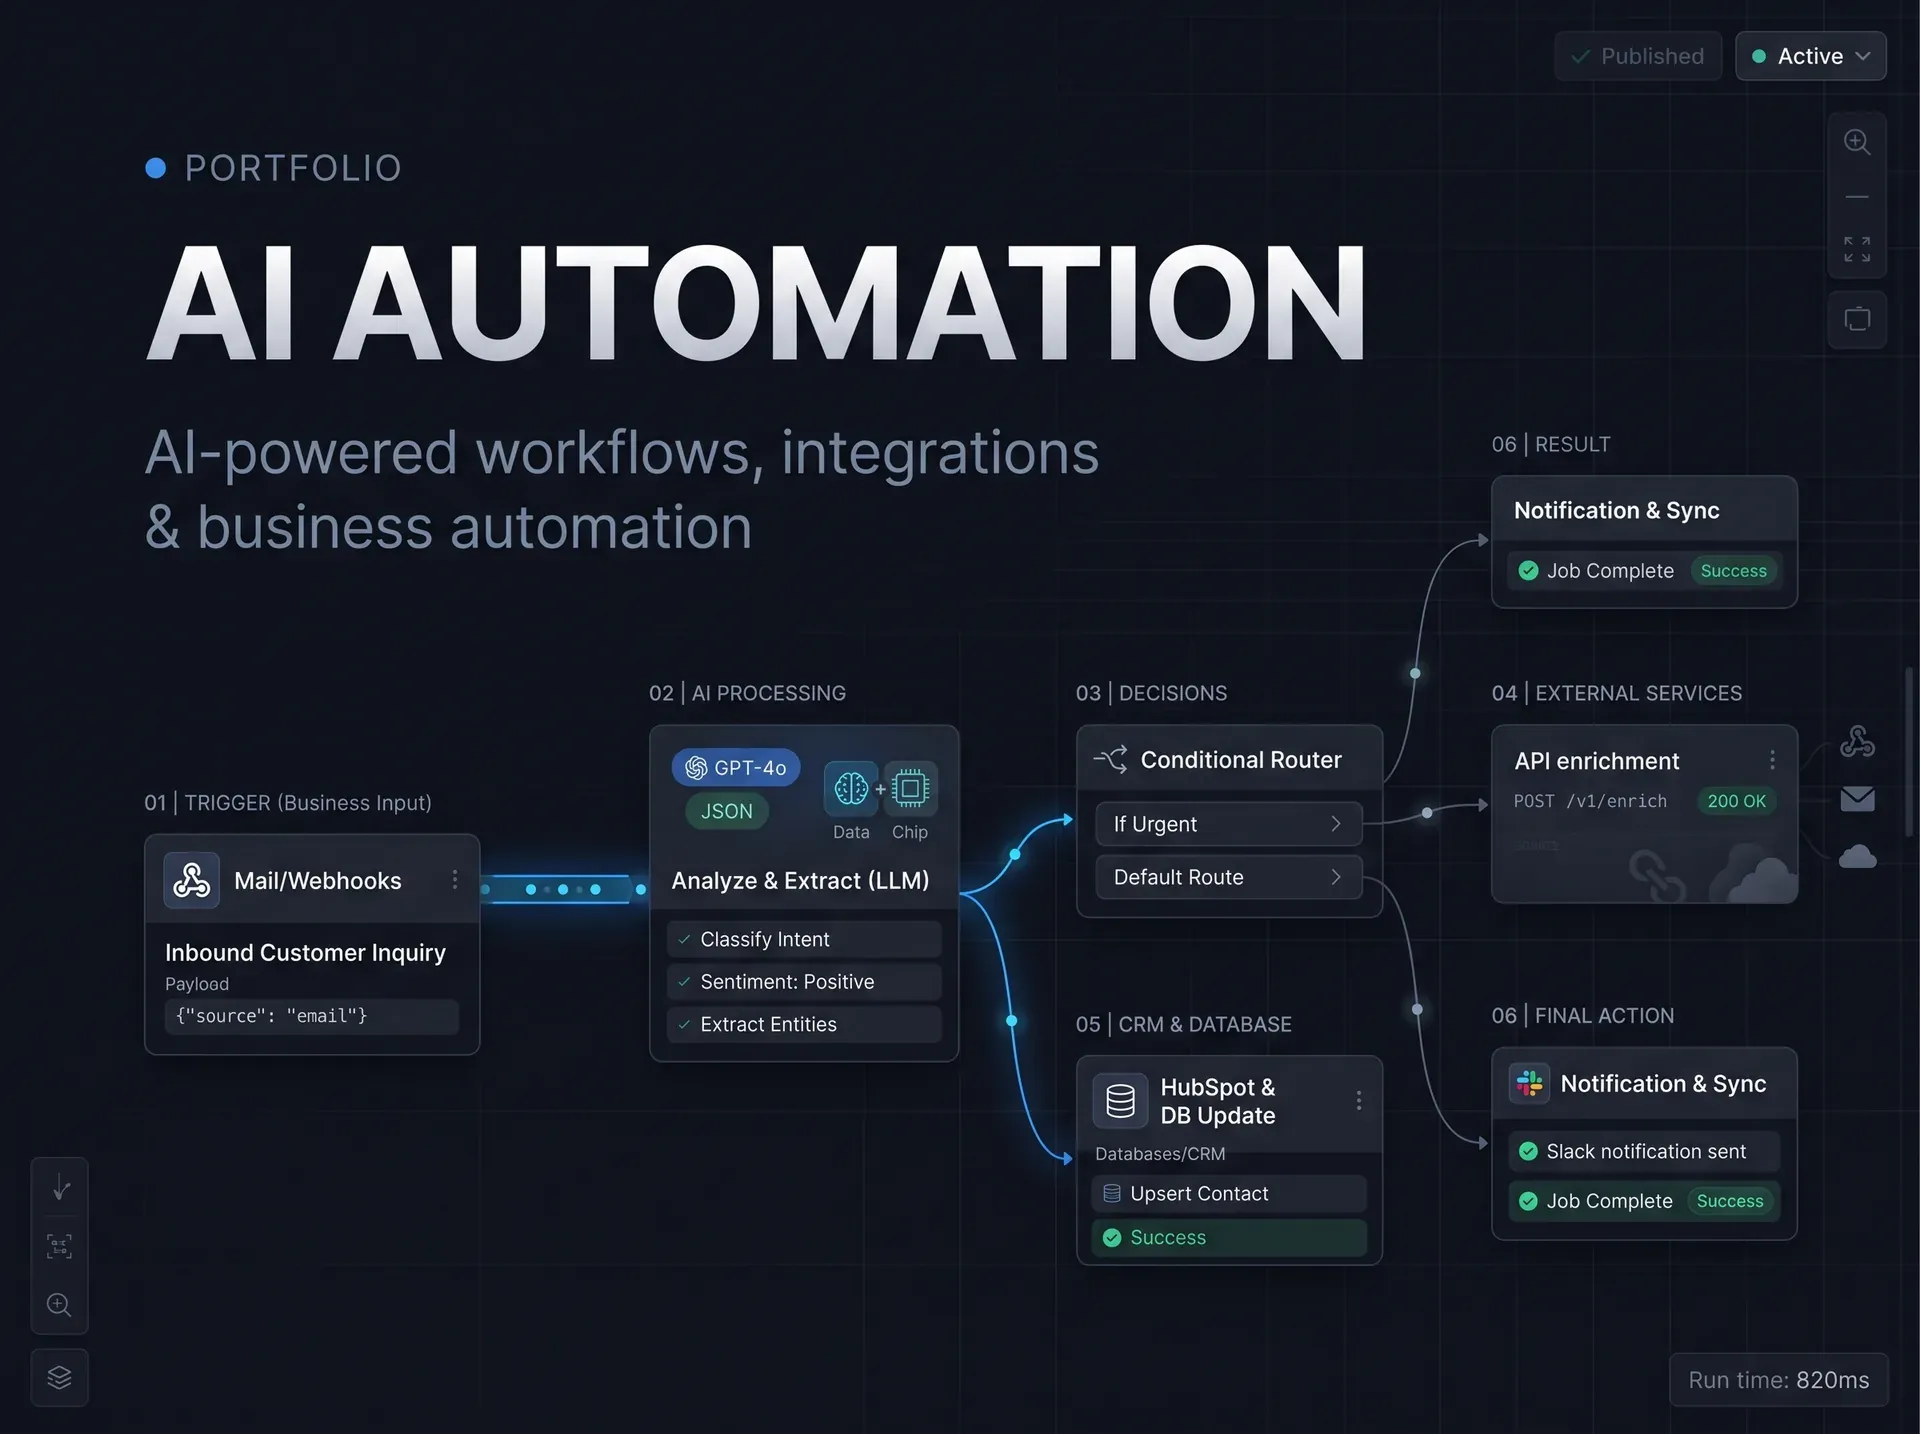
Lead Hunter AI — Autonomous Multichannel Lead-Gen & Scoring Agent
Enterprise RAG — High-Load 65k+ Chunk Knowledge Engine & AI Gateway
Like our engineering approach?
We will architect and deploy a robust system for your business — from architecture to launch and support.